Always Updating Lists
•
October 9, 2026
•
8 min read
Rechecked October 10: all 19 OpenRouter decision-model entries, with exact IDs, context limits, input/output and cache-read prices, free variants, and API differences. Includes Clef’s serving limit and Tev1’s Chat Completions interface.
AI Models
•
October 4, 2026
•
3 min read
OpenRouter chat produced a detailed glass-crane SVG, while globe requests hit provider rate limits and the game retry returned no visible HTML.
AI Models
•
October 4, 2026
•
3 min read
Three original browser artifacts from OpenRouter chat, with an SVG result, a globe import failure and retry, and a wizard game with a confirmed restart defect.
AI Models
•
October 4, 2026
•
2 min read
A source-based look at Unbiased’s composite-model preview, its lower token rates, preliminary evaluations, and the implications of a changing serving stack.
AI Models
•
October 4, 2026
•
2 min read
Why Sol Pro is an execution mode of GPT-6.1 Sol, how it differs from reasoning effort, and why equal token rates can produce different task bills.
AI Models
•
October 4, 2026
•
2 min read
Verified GPT-6.1 Sol limits and pricing, the Responses API tool contract, and a practical way to evaluate a migration from GPT-6 Sol.
AI Models
•
October 4, 2026
•
2 min read
The discounted Sonnet 5.5 batch variant, its asynchronous execution contract, and the workloads that can tolerate delayed results.
AI Models
•
October 4, 2026
•
2 min read
Anthropic’s Sonnet 5.5 announcement, current OpenRouter route limits, and how to interpret vendor speed and cost-per-task claims.
AI Models
•
October 4, 2026
•
2 min read
How OpenRouter’s Jev Router uses TypeSafe’s decision model to select a generation model, and why its pricing is not a free-token offer.
AI Models
•
October 4, 2026
•
2 min read
Mk1.5’s audio/video inputs, spatial annotations and tool use, plus the context-limit difference between its announcement and OpenRouter’s route.
AI Models
•
October 4, 2026
•
2 min read
Fireworks’ specialized Kimi K3 derivative, its reported reasoning-token reductions, and how to evaluate cost per completed task.
AI Models
•
September 28, 2026
•
2 min read
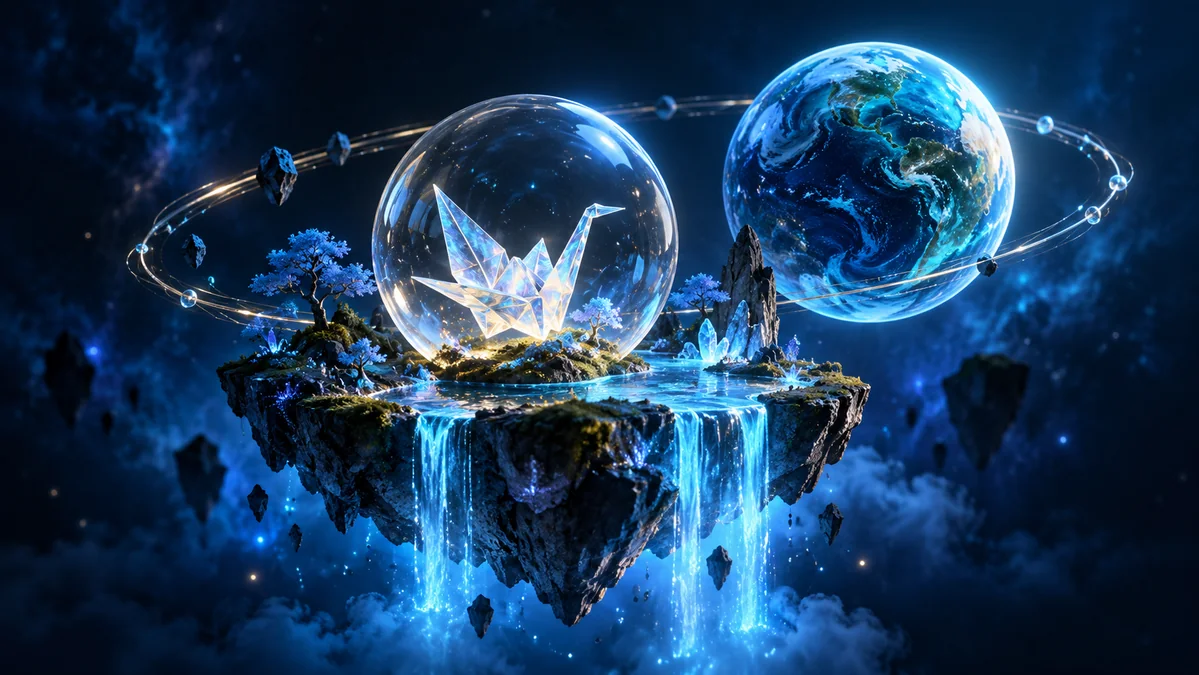
A concise hands-on look at three Claude Sonnet 5.5 Medium HTML artifacts: a glass-and-origami SVG, an interactive procedural globe, and a floating-island wizard game.
AI Models
•
September 23, 2026
•
3 min read
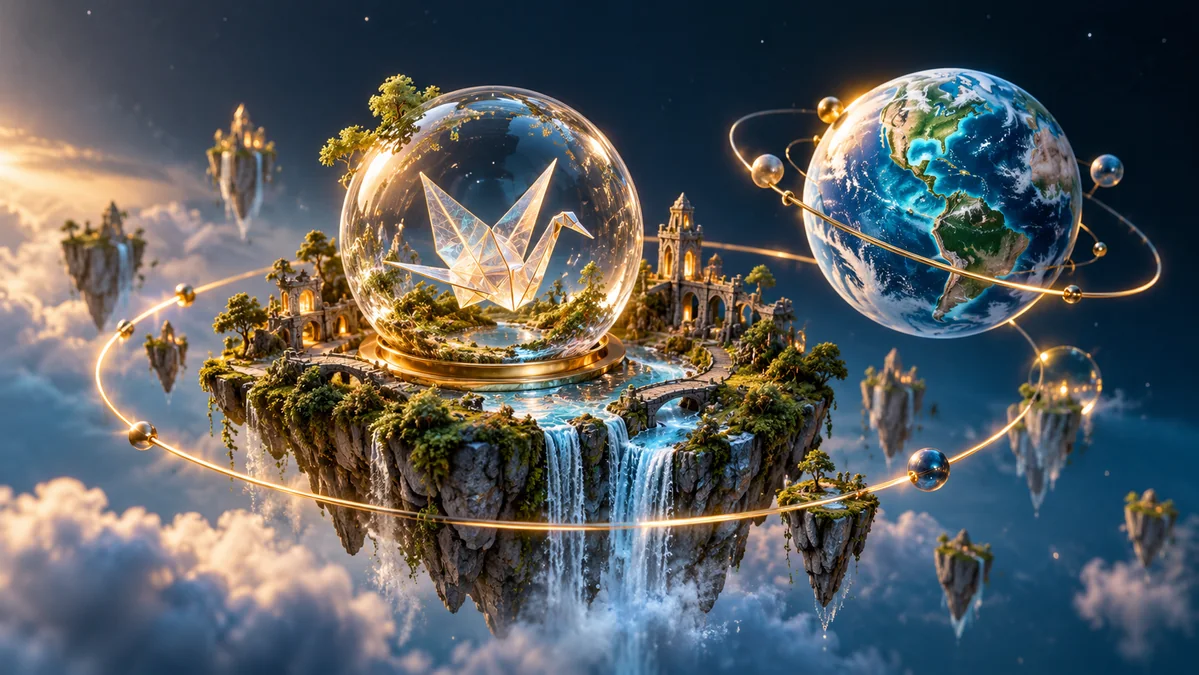
A hands-on look at three GPT-6 Luna creative-coding artifacts: the Aetherfall wizard game, Pelagic procedural globe, and glass origami crane, with interactive previews and scope notes.
AI Models
•
September 23, 2026
•
2 min read
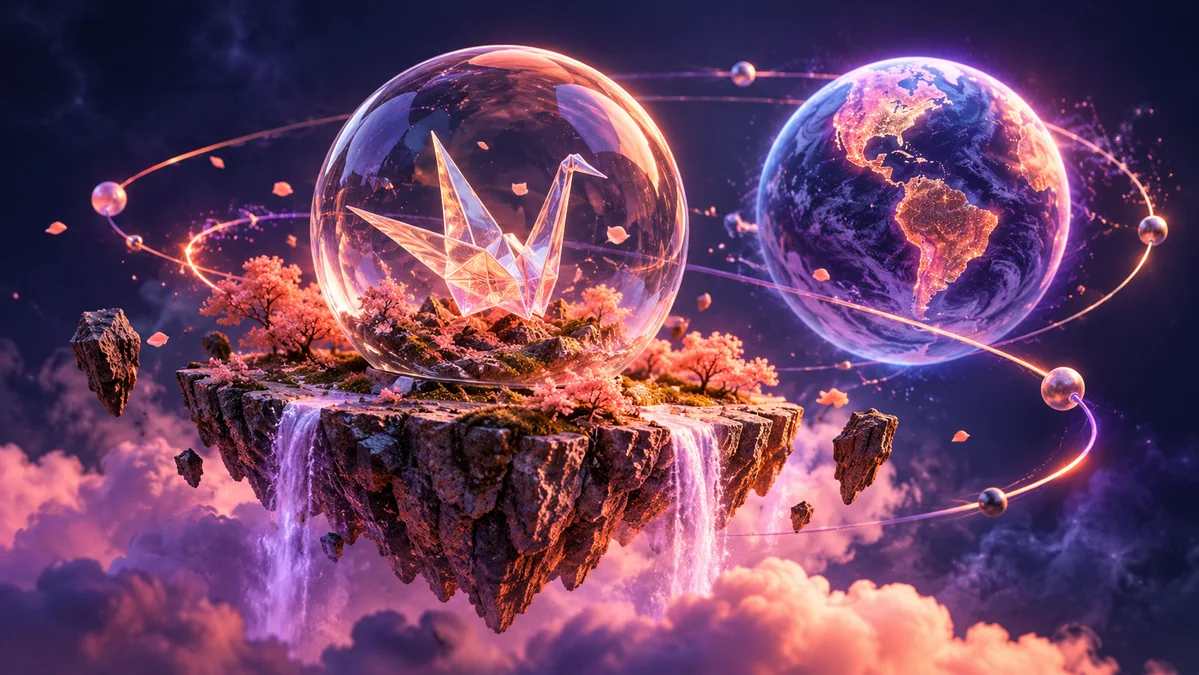
Explore three supplied GPT-6 Sol browser artifacts: Floating Isles wizard quest, Blue Horizon procedural globe, and a glass-sphere origami crane, embedded as isolated previews.
AI Models
•
September 21, 2026
•
3 min read
Hands-on Grok 4.7 CLI test with embedded SVG crane and interactive Three.js globe HTML, browser observations, and an explicit account of the wizard-game request that failed at the CLI quota limit.
AI Models
•
September 20, 2026
•
3 min read
A fact-checked guide to Gemini 3.8 Flash covering Google's documented 1,048,576-token input window, 65,536-token output limit, multimodal support, thinking levels, tools, and introductory $0.75/$3.75 per million-token pricing.
AI Models
•
September 19, 2026
•
6 min read
AI safety is becoming an immediate engineering and governance problem: increasingly capable agents can act in the world, so evaluation, access controls, monitoring, and accountability need to grow alongside capability.
AI Models
•
September 10, 2026
•
7 min read
A hands-on DeepSeek V4.1 Flash review covering its 552B MoE architecture, compressed KV cache, official agent benchmarks, and three interactive creative-coding tests.
Platform Guides
•
September 7, 2026
•
5 min read
Learn how to choose a provider by capability and connection type, securely connect it, and equip only the models you need in AcceleratedLogic AI.
AI Models
•
September 6, 2026
•
11 min read
IFM's six-model K2 Horizon family combines open weights, training artifacts, a reported 512K context window, and agentic benchmarks. What developers should know.
AI Models
•
September 3, 2026
•
7 min read
GPT-6 Astra shifts ChatGPT from generating advice toward completing long-running work inside real software. We separate the verified launch details from the AGI rhetoric and examine its computer-use ambitions, restricted cyber capabilities, safeguards, availability, and unanswered pricing questions.
AI Models
•
September 2, 2026
•
4 min read
A dated review of Meta's first-party Muse Spark 1.3 model, feature, context-window, pricing, and API documentation. Unsupported benchmarks and release predictions from the earlier draft have been removed.
AI Models
•
September 1, 2026
•
3 min read
Anthropic reports a Terminal-Bench-Science gain for Fable 5.1 and a 75% lower cache-read price than Fable 5. This guide explains the benchmark caveats, effort settings, safeguard differences, and how to evaluate actual cost per accepted task.
AI Models
•
August 28, 2026
•
3 min read
Tencent describes Hy4-preview as a 770B model with 49B active parameters and a context window over one million tokens. Review the company's internal benchmark disclosure, dated access offer, and an archived single-run visual coding sample.
AI Models
•
August 26, 2026
•
2 min read
Z.ai says it evaluated GLM-5.3-Flash anonymously as Ox Alpha before release. Review the vendor's model description and learn how to verify model IDs, pricing, availability, and data terms across different API routes.
Always Updating Lists
•
August 22, 2026
•
5 min read
Updated Copilot credit-based allowances and eligibility programs, plus Cursor Hobby, Gemini CLI, Cline, OpenCode, Aider, and Ollama. Separate free client software, hosted quotas, subscription costs, and local inference.
AI Models
•
August 14, 2026
•
2 min read
Z.ai describes GLM-5.3 as a post-training update with stronger coding and reported cybersecurity capabilities. This source-based guide separates the company's benchmark claims from independent evaluation and outlines safe testing practices.
AI Models
•
August 13, 2026
•
4 min read
Google documents Gemini 3.7 Flash with a 1,048,576-token input limit, 65,536-token output limit, multimodal inputs, and no free API tier. The guide includes accurate current pricing and scoped archived code examples.
AI Models
•
August 13, 2026
•
4 min read
On August 13, 2026, Google released Gemini 3.7 Flash and Gemini 3.5 Flash-Lite. Designed around speed, lower output token usage, and 1M context windows, they offer a highly practical workhorse foundation for coding, agentic workflows, document processing, and computer use.
AI Models
•
August 12, 2026
•
4 min read
DeepSeek's current V4 Pro 0813 API documentation lists a 1M-token context, 384K output limit, and peak/off-peak pricing that varies with cache status. Two archived code outputs are presented as examples, not rankings.
AI Models
•
August 12, 2026
•
4 min read
Grok 4.6 has a documented 500K context window and API prices that vary for cached input and long prompts. Read the official benchmark caveats and inspect two archived code samples without treating them as a model ranking.
AI Models
•
August 11, 2026
•
2 min read
NVIDIA lists Nemotron 3.5 Lightning as a 30B/3B-active hybrid model with up to 1M context and the OpenMDW 1.1 license. Separate vendor-reported checkpoint scores from one archived, non-executable coding sample.
AI Models
•
August 10, 2026
•
2 min read
Meta's Apache 2.0 Muse Glimmer has about 30B parameters, image input, and a 131K model-card context. Compare BF16 and GGUF options, check real hardware requirements, and avoid treating a quant label as a benchmark result.
AI Models
•
August 6, 2026
•
3 min read
Compare Ling-3.0-tiny's 7.9B total/1.3B active model with Ling-3.0-flash's 124B total/5.1B active model. Review official licenses, hardware guidance, and benchmark methodology before choosing a hosted or local deployment.
AI Models
•
August 5, 2026
•
2 min read
Meta lists Muse Spark 1.2 as a coding-focused model in the Muse family and now highlights Spark 1.3 as the latest release. Verify the exact API route, pricing, and limits, then compare versions on your own repository tasks.
AI Models
•
August 3, 2026
•
4 min read
Alibaba's Qwen3.8-Max announcement and Model Studio documentation describe a long-context, multimodal hosted model. This article focuses on how to evaluate its fit for a real workflow rather than treating public scores as a universal value ranking.
Platform Guides
•
August 1, 2026
•
4 min read
A decision framework for comparing budget models using cost per accepted task, realistic retries, output quality, data handling, and deployment fit.
Always Updating Lists
•
August 1, 2026
•
5 min read
Updated directory of 15 model developers and six cloud or routing services. Find first-party model sources, current API IDs, access requirements, modalities, licenses, and pricing; includes decision-model discovery guidance.
AI Models
•
July 31, 2026
•
2 min read
Celeris-1's current API documentation lists an 8,192-token total window and output limits in 256-token blocks. Review its provider-published MMLU-Pro latency methodology, $0.20/$0.70 per-million pricing, and request handling requirements.
AI Models
•
July 31, 2026
•
2 min read
DeepSeek now documents V4.1 Flash as its current Flash API model and says older V4 Flash aliases route to it. See what changed, how to identify the model an API call actually uses, and how to retest legacy workloads.
AI Models
•
July 31, 2026
•
4 min read
Thinking Machines Lab has officially released Inkling Small, an efficient 276B MoE open-weights model with 12B active parameters, 1M context, native audio/image reasoning, and controllable thinking effort under Apache 2.0.
Platform Guides
•
July 30, 2026
•
4 min read
A practical model-selection guide covering task definitions, primary-source checks, reproducible evaluations, long-context tests, and provider operations.
AI Models
•
July 30, 2026
•
4 min read
Agnes has deprecated the hosted Alpha API. Learn how to migrate to agnes-2.5-pro, check current pricing, or self-host the Apache 2.0 weights.
AI Models
•
July 29, 2026
•
4 min read
The Open Secure AI Alliance is a 37-member initiative announced in July 2026. This article reviews its stated focus and offers practical checks developers can use when assessing security projects.
AI Models
•
July 28, 2026
•
4 min read
Moonshot AI released a dense technical report for Kimi K3, a 2.8T parameter model activating 104B per token. Here is what KDA, AttnRes, LatentMoE, SiTU-GLU, and Quantile Balancing actually mean.
AI Models
•
July 26, 2026
•
2 min read
Compare Claude Opus 5 and its newer Opus 5.5 release using Anthropic's current model IDs, token and cache-read prices, and a task-based cost evaluation.
AI Models
•
July 22, 2026
•
4 min read
OpenAI and Hugging Face published separate accounts of a July 2026 incident involving agents in internal cybersecurity evaluations. This article distinguishes their statements and explains the role of GLM-5.2 in Hugging Face's forensic analysis.
AI Models
•
July 21, 2026
•
7 min read
A source-based analysis of U.S. and Chinese open-weight releases, the difference between open weights and open-source AI, and the potential benefits and costs for developers, businesses, and policymakers.
AI Models
•
July 21, 2026
•
4 min read
A source-backed overview of Poolside's Laguna S 2.1 release and the questions developers should answer before adopting an open-weight coding model.
Platform
•
July 21, 2026
•
4 min read
Accelerated Logic AI is a browser-based workspace for configured local and hosted models, role-scoped agent workflows, local-first storage, optional Google Drive backup, and focused browser tools. The guide describes its data paths and current feature boundaries.
AI Models
•
July 21, 2026
•
4 min read
A source-backed look at the Motif 3 release, its published model details, and how developers can evaluate a new open-weight model without relying on regional leaderboard claims.
AI Models
•
July 18, 2026
•
3 min read
OpenAI describes GPT-Red as an internal model for testing prompt-injection defenses. Learn what its vendor-reported results show, what they do not prove, and how to test an AI application's tools and permissions.
AI Models
•
July 16, 2026
•
4 min read
A source-backed guide to Kimi K3’s reported capabilities and how teams can test long-context retrieval, coding, multimodal work, deployment fit, and operational cost with their own tasks.
AI Models
•
July 16, 2026
•
7 min read
The variety of different AI models is increasing every day. With so many options out there, how can you actually know which ones are the best? The answer: benchmarks.
AI Models
•
July 15, 2026
•
2 min read
Thinking Machines Lab lists Inkling at 975B total and 41B active parameters with text, image, and audio input. Its model card describes multi-GPU requirements that make the full checkpoint unsuitable for ordinary consumer desktops.
AI Models
•
July 14, 2026
•
4 min read
A task-based evaluation guide that separates provider claims from measured results and explains how to compare the cost, reliability, and oversight needs of an agentic model.
AI Models
•
July 14, 2026
•
6 min read
PrismML released Bonsai 27B, a 1-bit and ternary quantized 27B model based on Qwen3.6-27B that runs locally on smartphones and laptops with a footprint as small as 3.9 GB.
AI Models
•
July 13, 2026
•
7 min read
Compare Qwen, DeepSeek, GLM, Kimi, and other models using checkpoint licenses, deployment needs, API data terms, current pricing, and repeatable tests.
AI Models
•
July 9, 2026
•
3 min read
Compare GPT-5.6 Sol, Terra, and Luna using OpenAI's current model IDs, 1.05M context limits, per-token prices, and a repeatable cost-per-success evaluation method.
Platform Guides
•
July 9, 2026
•
5 min read
An overview of role-based multi-agent workflows, where they may help, how errors can propagate, and how to account for added cost and latency.
Platform Guides
•
July 8, 2026
•
5 min read
Compare Google Gemini, Cloudflare Workers AI, OpenRouter, Groq, and Ollama for AI prototypes. Check current free limits, privacy terms, rate limits, and local hardware costs before choosing.